Enumerates the hardware
Reads the CPU's capabilities and finds installed CUDA and Vulkan libraries or the Metal framework. Shared CPU/GPU memory is counted once, as one pool.
It compiles for the machine it lands on, schedules models across every core and GPU, and pages them through memory as demand changes.
An operating system for LLM inference
Today an inference engine is a program you fit the machine to: pick a backend, size the model to the card, restart to change anything. jitllm turns that around. It starts with the model and the machine, then compiles, places and pages the work for whatever is in front of it, and keeps doing so while it serves.
A small simulation of the runtime: models load from .jlm, placement picks a device for every block, blocks page from disk straight onto that device, and a token runs through them in order, growing each device's KV cache. Blocks and their KV move between devices only when placement changes. Click a model to send it a request, add CPUs and GPUs, or change where the blocks go.
Same machine, same pass, same GGUF file. Ratios are jitllm ÷ the other engine; above 1.00× means jitllm is faster.
4.62×
llama.cpp's prefill on Qwen3-Next-80B-A3B
4× V100, 512-token prompt
5.5×
vLLM's throughput, 128 sequences batched
Llama-3.1-8B Q4_K_M, one V100
34/35
models prefill faster than on llama.cpp
V100, 360M to 120B, 1 to 5 GPUs; the 35th level at 1.00×
35/35
models decode faster than on llama.cpp
V100, 1.01× to 1.35×
jitllm speed -p 512 -n 128 -r 2 against llama-bench -p 512 -n 128 -ngl 99 -r 3 on the file jitllm converted from; vLLM 0.18.1, generated tokens over wall clock. Q4_K_M unless named. One pass per host. Hosts, method and the CPU board.
Pick an engine. Every feature is checked against that project's own documentation and source, and links to it.
Checked against each project's own documentation and source; every mark links to it. Out of date? Tell us.
It is one process. Inside it, models are the programs, their blocks are the threads, and every CPU core and accelerator on the machine is somewhere they can run.
Placement, paging and tuning are automatic, and every one of those decisions can be forced by the application.
.jlm containerEvery architecture, kernel and path keeps all five.
Four subsystems between your application and the hardware.
Reads the CPU's capabilities and finds installed CUDA and Vulkan libraries or the Metal framework. Shared CPU/GPU memory is counted once, as one pool.
Native x86-64 and ARM64 code and GPU kernels, specialized for the model's shapes and weight formats, then tuned by measurement: kernel layouts, worker counts, tiles, splits.
Blocks run on the CPU or on any GPU, spread across several at once. Placement can change between tokens: grow onto a GPU, give blocks back as context grows, tune the split.
Weights, experts, KV pages and recurrent state move between VRAM, RAM and storage. Run models larger than RAM, and make room for another model without discarding a conversation.
The executable format
An OS loads programs from a format built for loading. .jlm is that for models: GGUF or Hugging Face weights, with their quantization preserved, laid out once so evicting and reloading them during inference never repeats the preparation.
One file carries the weights, configuration, tokenizer, chat templates and optional vision tower, for the CLI, the server, the desktop app and the Go library alike.
The formatQuantized weights are stored in the layout the GPU backends share, so a reload is a read.
Predictable block offsets and addressable expert ranges let the pager fetch only what a token uses.
CUDA, Vulkan and Metal read the same container, so execution can move between backends and reuse it.
One self-contained binary per program, for Linux, macOS and Windows on x86-64 and arm64. GPU backends use the drivers already on the machine; jitllm finds them at run time.
Install the CLI and the server from the latest release, then convert Qwen3-30B-A3B, a 30B mixture of experts that uses 3B per token (18.6 GB to download). On Windows: irm https://raw.githubusercontent.com/samyfodil/jitllm/main/scripts/install.ps1 | iex.
$ curl -fsSL https://raw.githubusercontent.com/samyfodil/jitllm/main/scripts/install.sh | sh
$ mkdir -p models
$ jitllm convert -o models qwen3-30b-a3b models/qwen3.jlmStart the API server with automatic device selection, then stream a chat from another terminal.
$ jitllmd serve -addr 127.0.0.1:8080 -models ./models \
    -load qwen3.jlm -id qwen3 -devices auto
$ curl http://127.0.0.1:8080/v1/chat/completions \
    -H 'Content-Type: application/json' \
    -d '{"model":"qwen3","stream":true,
"messages":[{"role":"user","content":"Hi"}]}'Chat, choose a model, convert it, and watch where every block of it sits. The engine runs inside the app's own process.
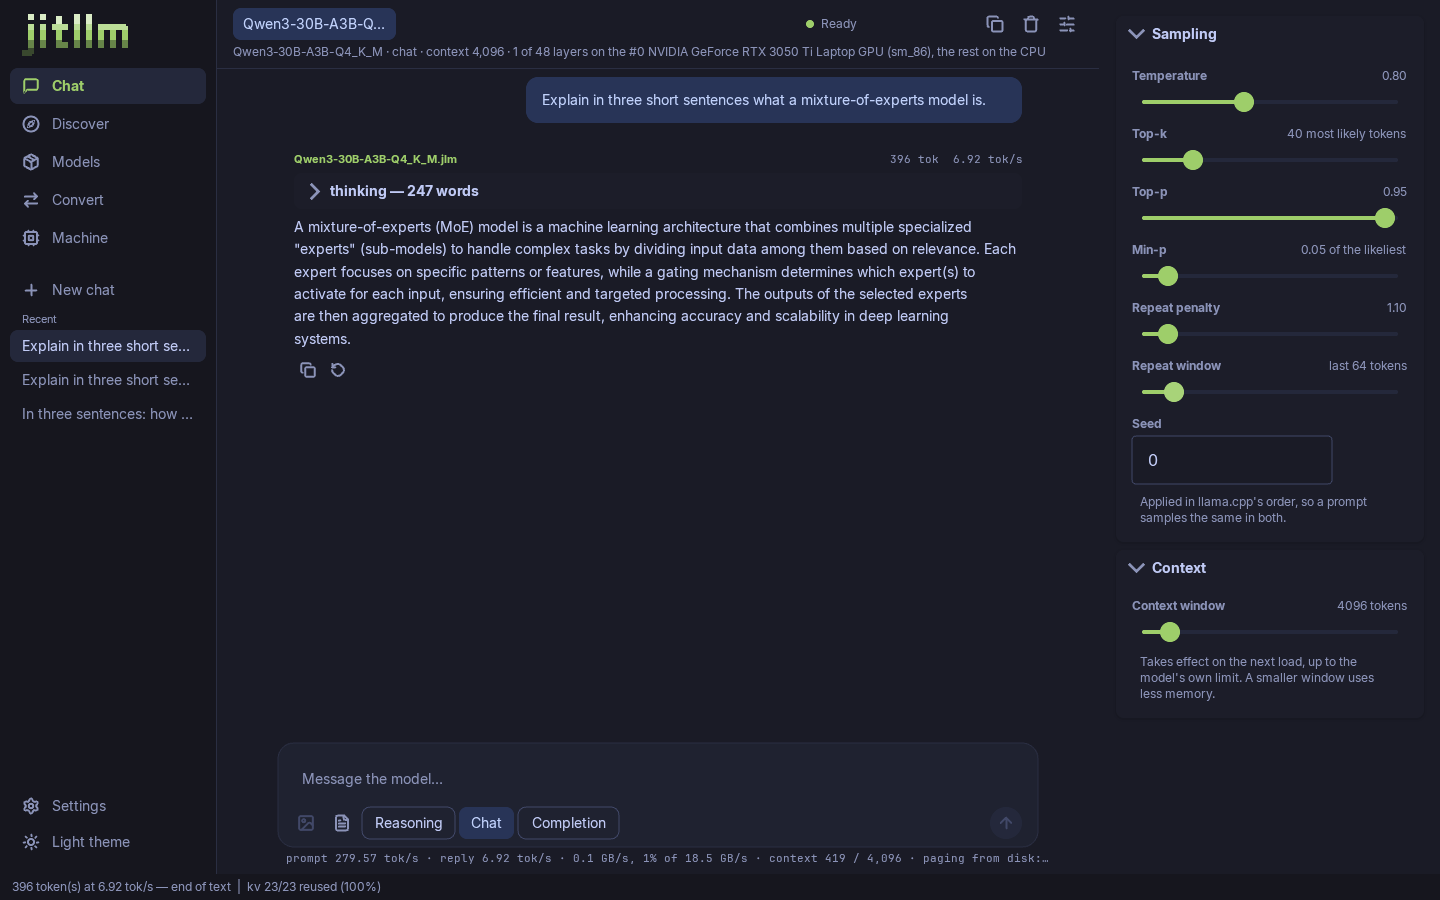
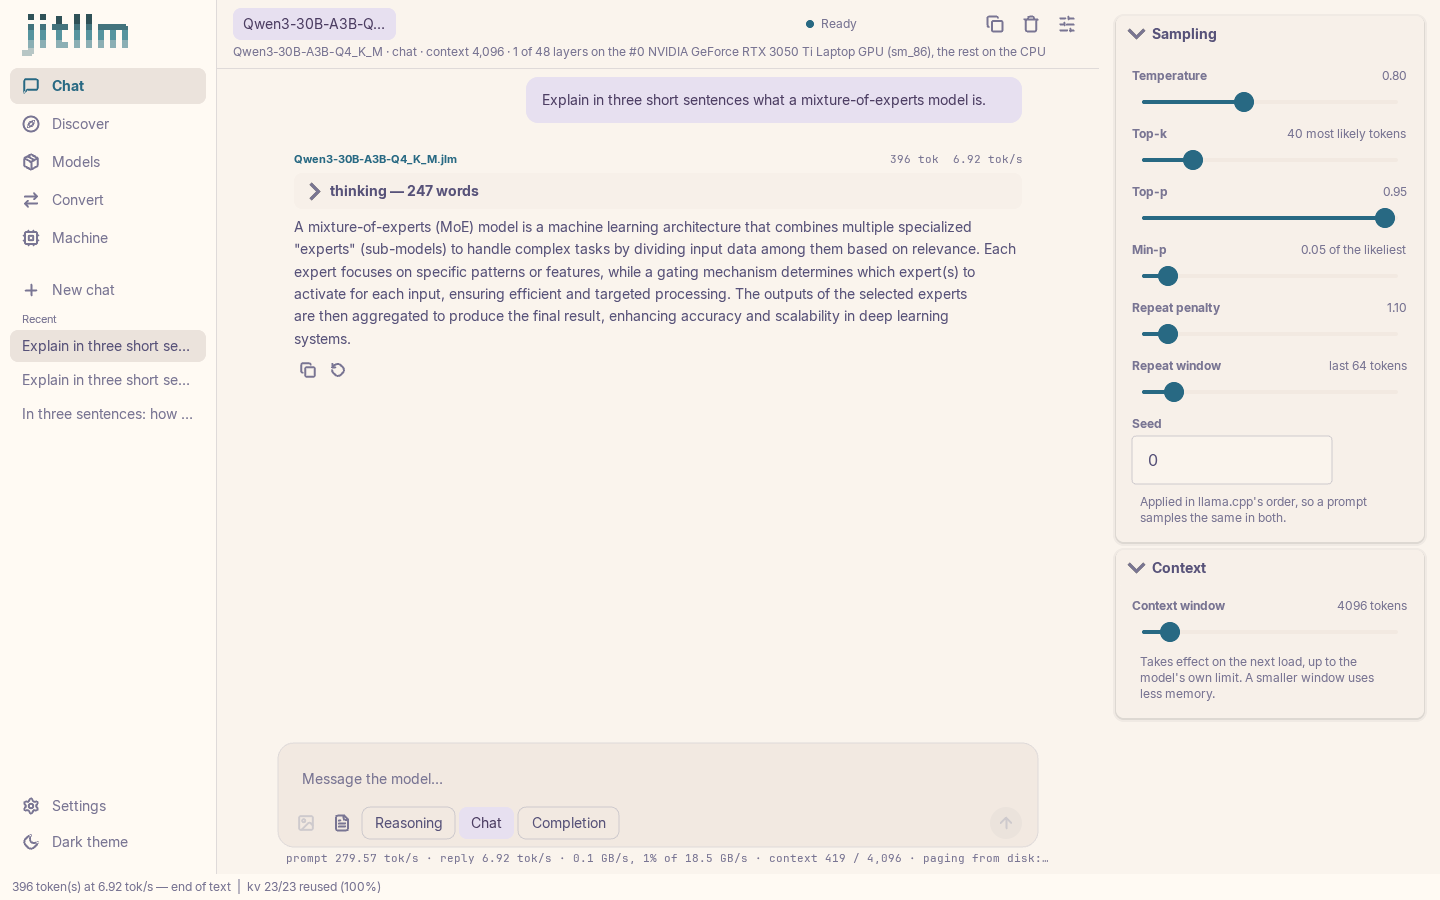
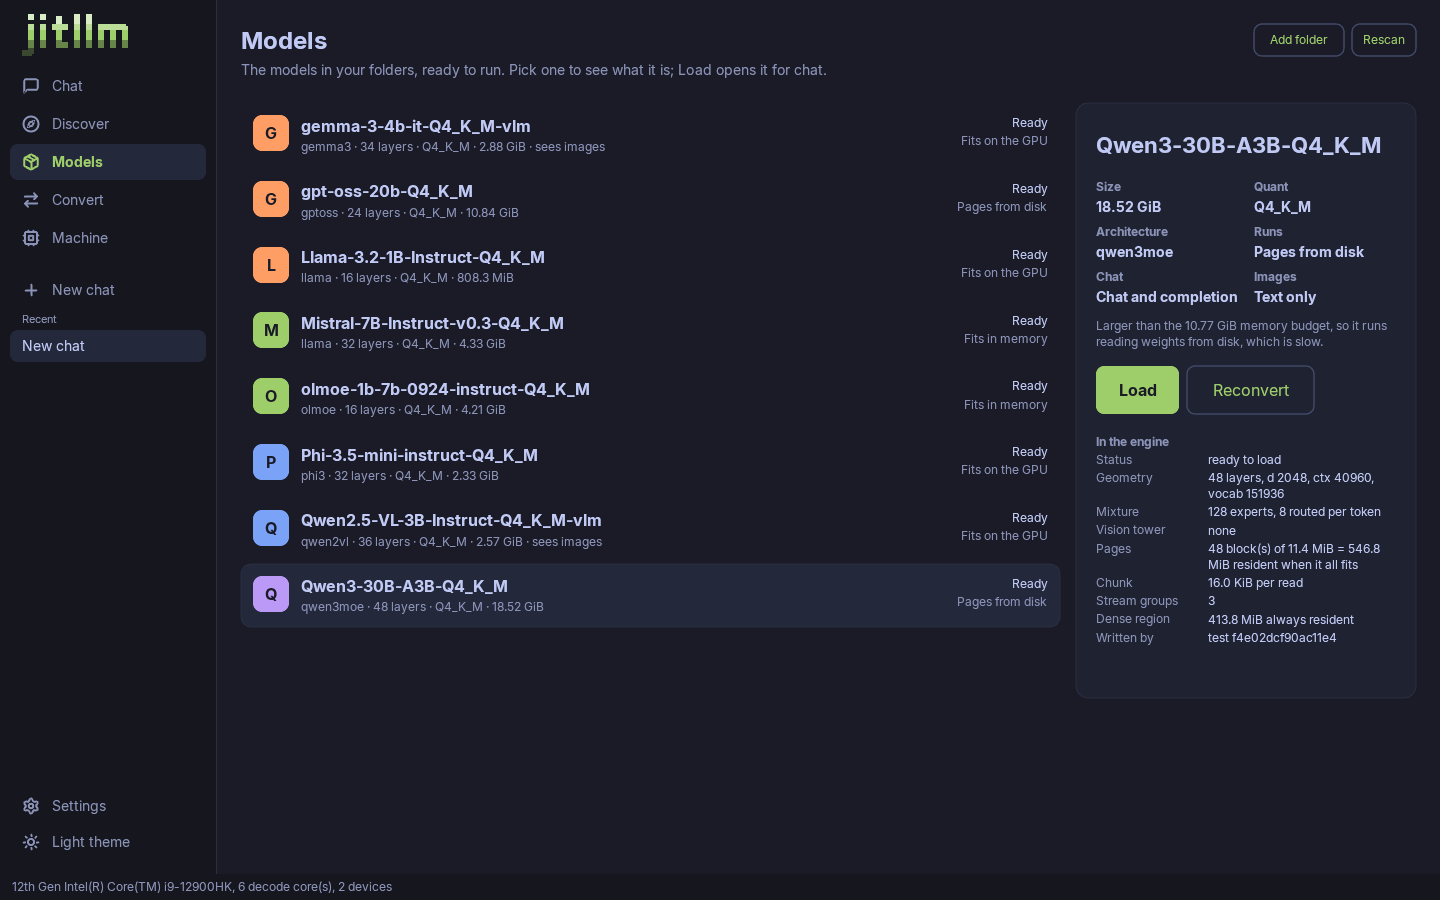
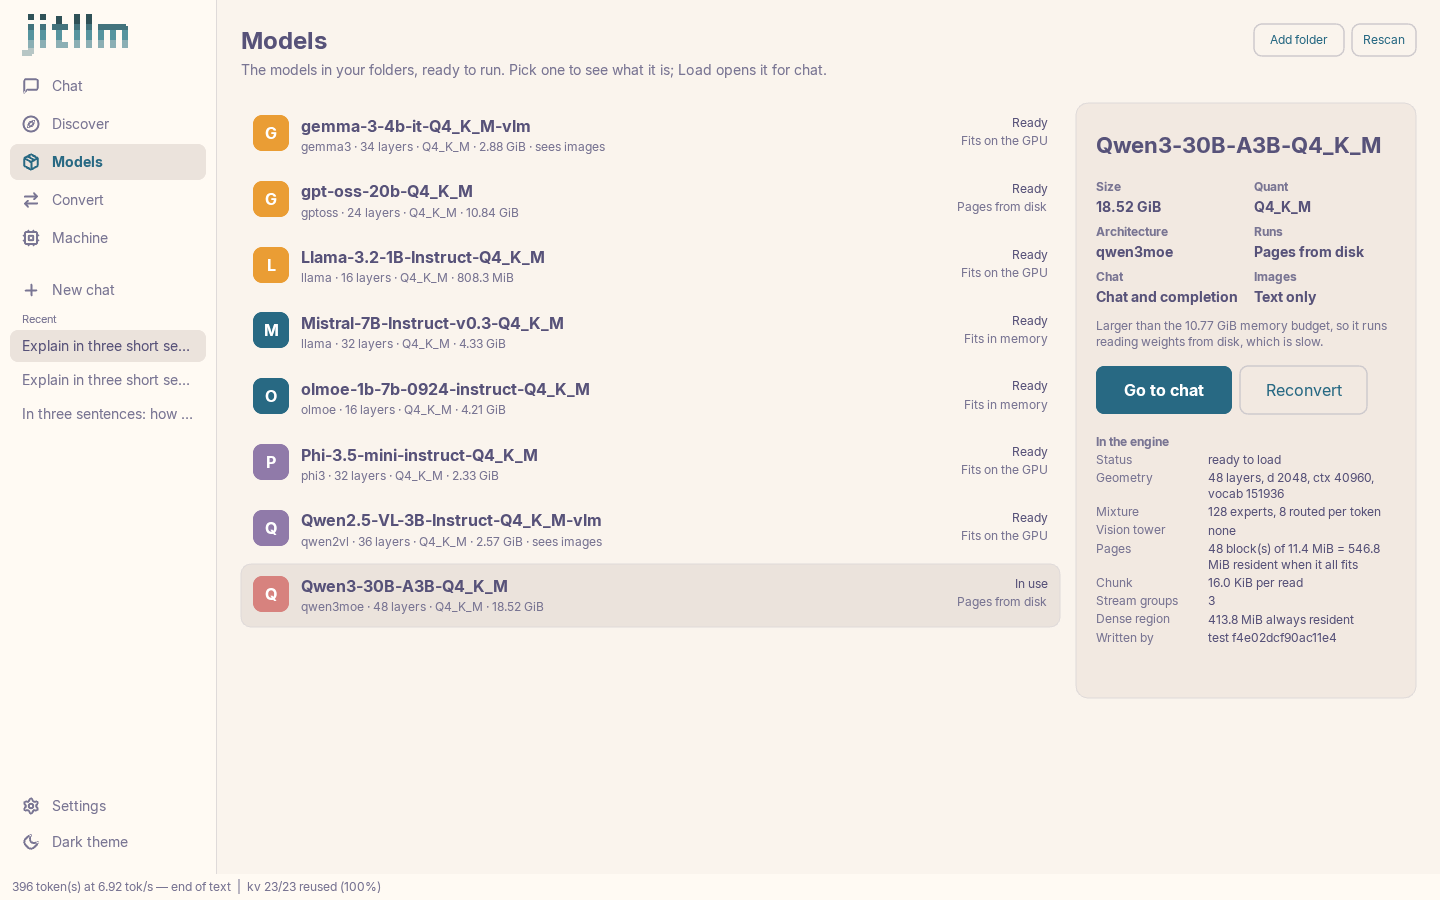
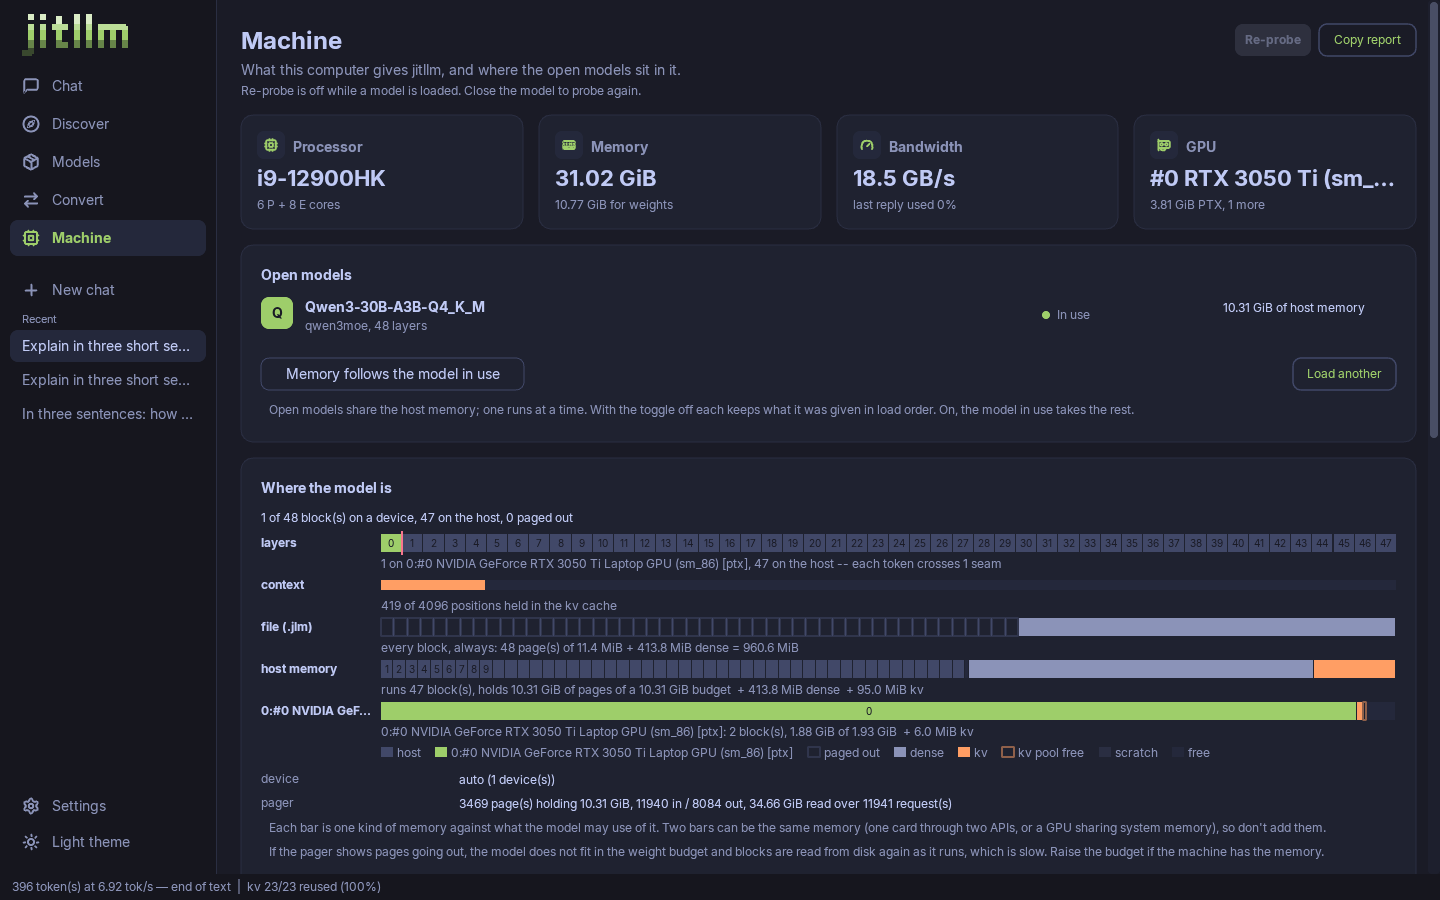
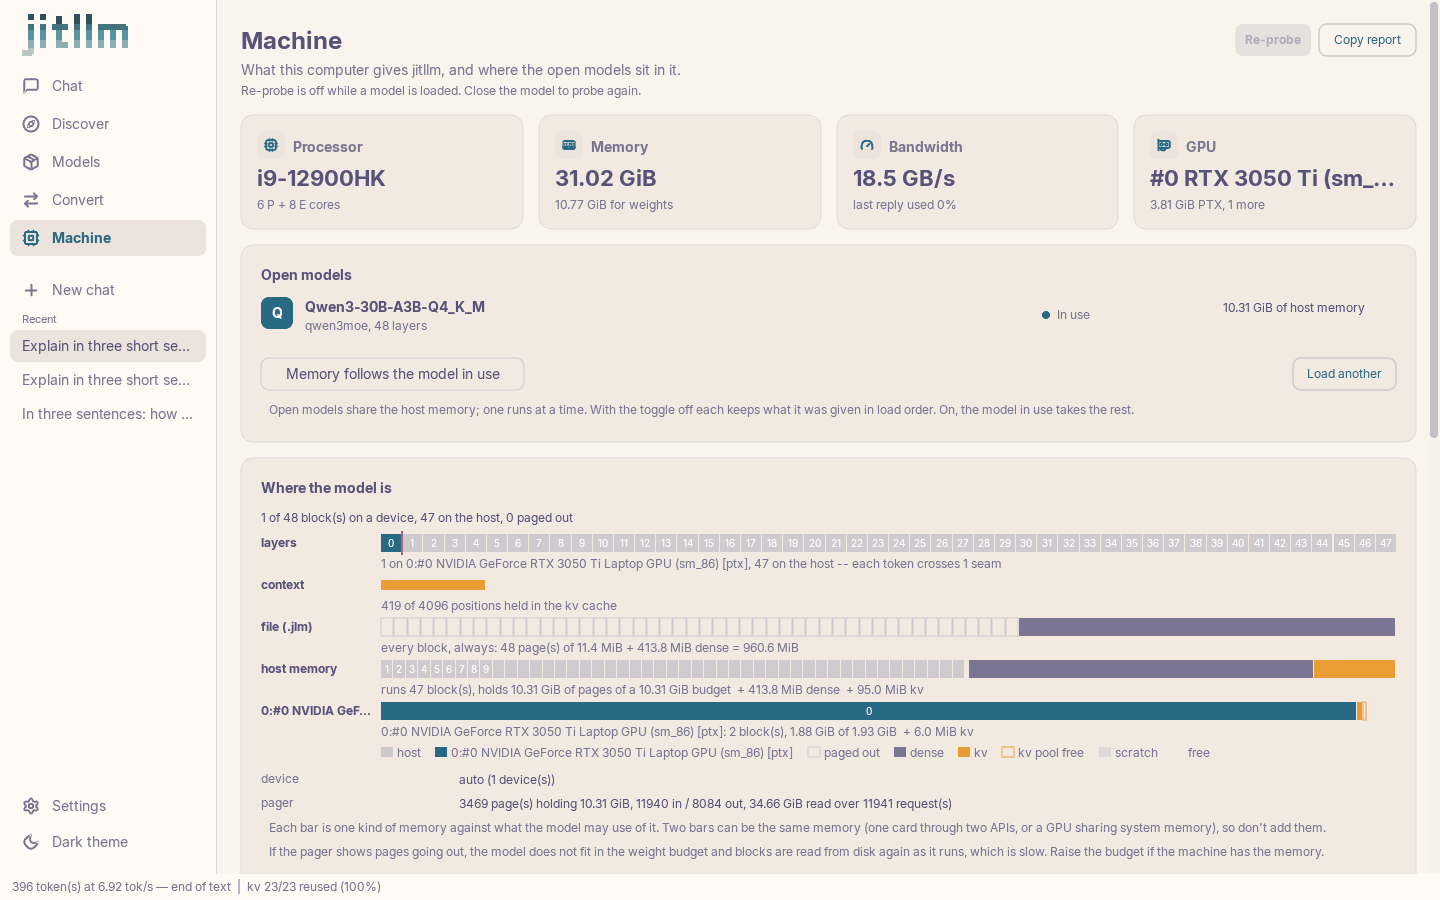
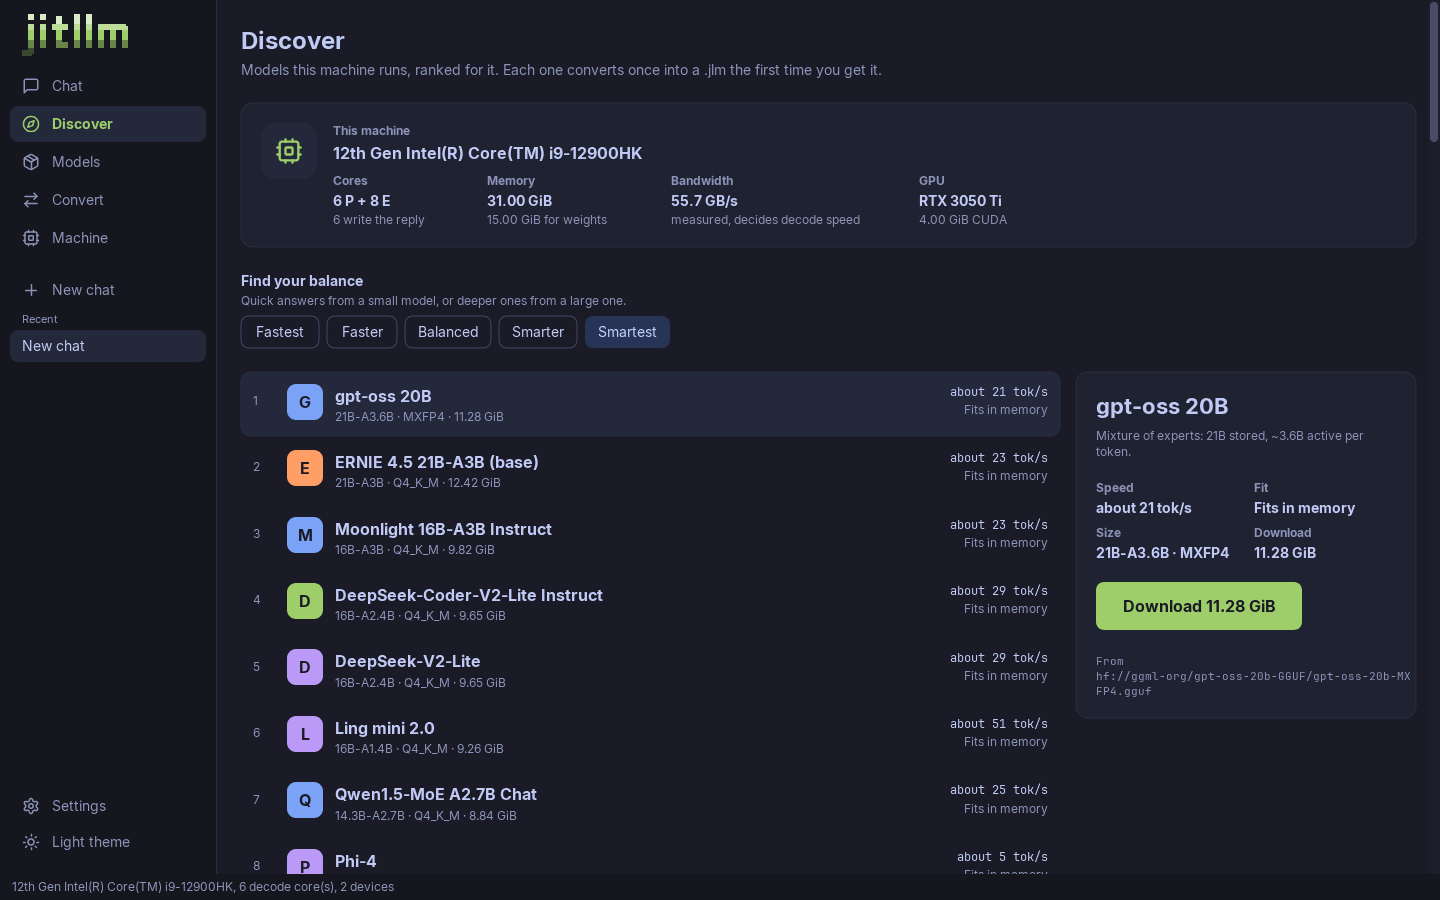
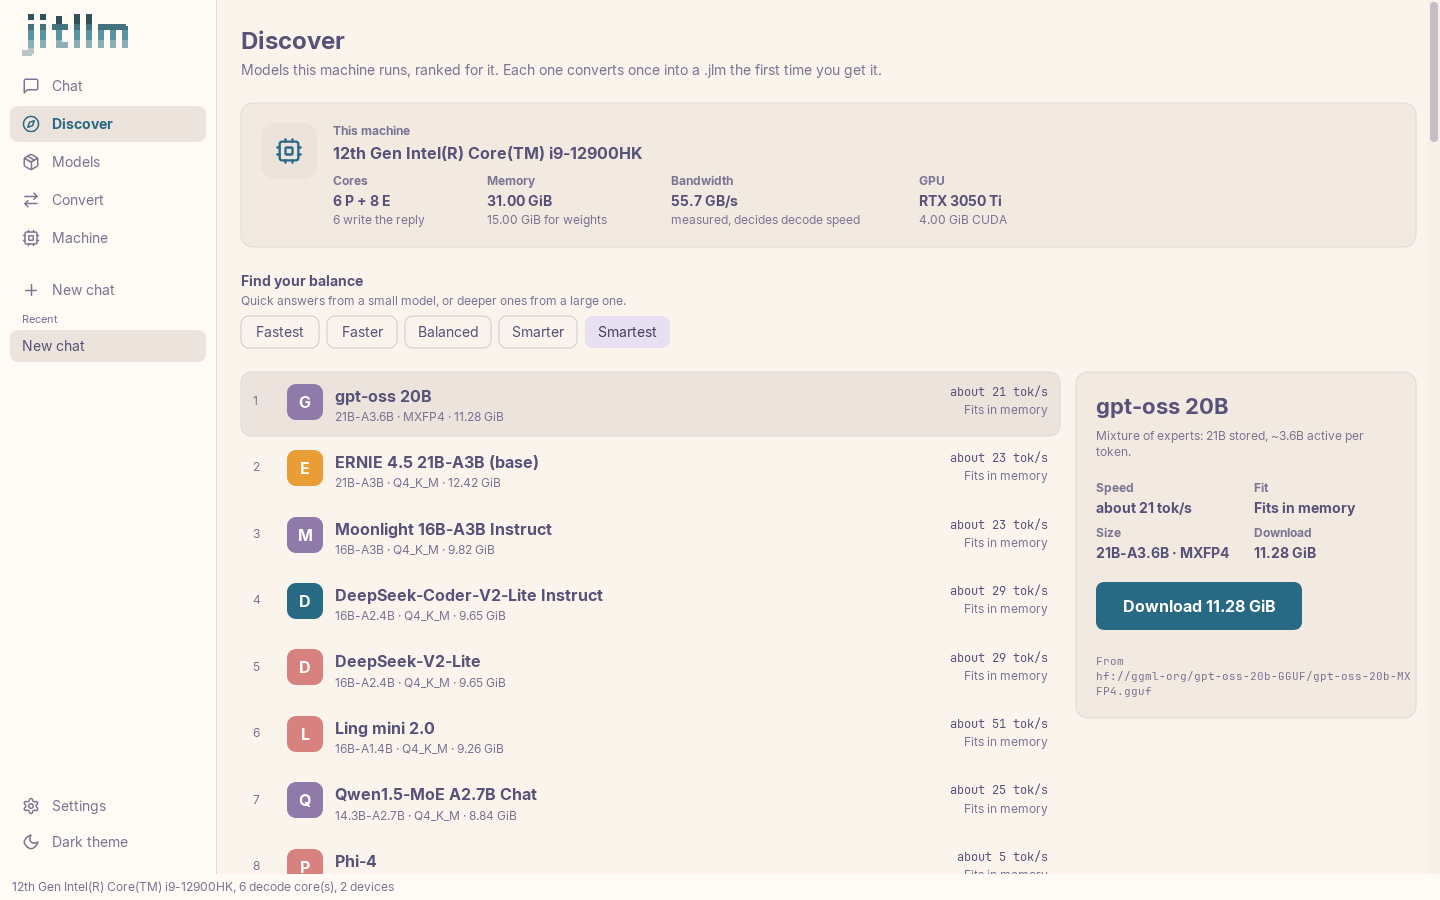
The same screens over SSH, sharing the desktop app's settings and chats. Move the model's blocks between the CPU and the GPU with the arrow keys; the conversation keeps its history.
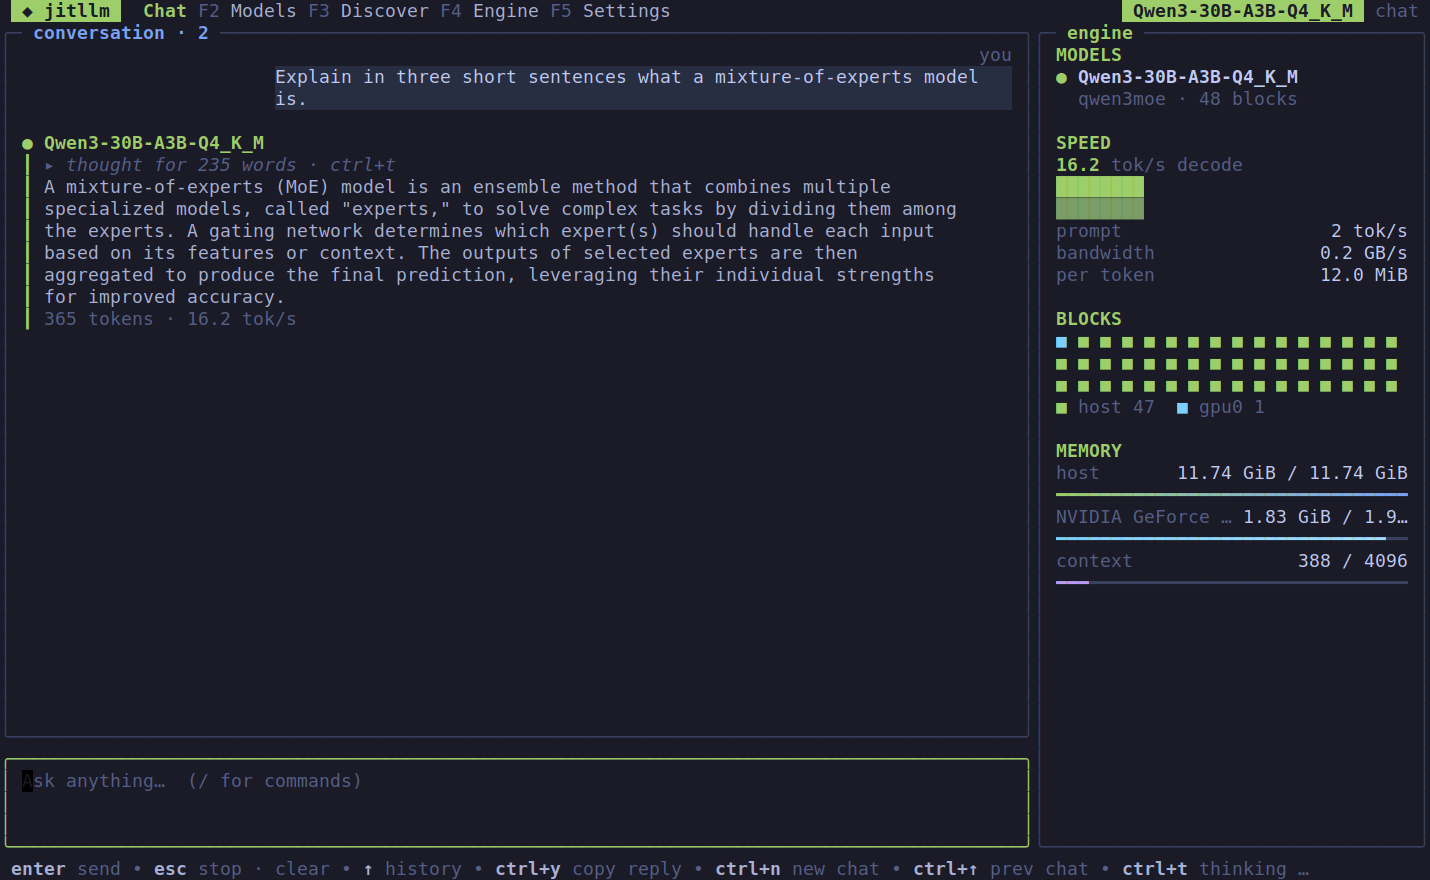
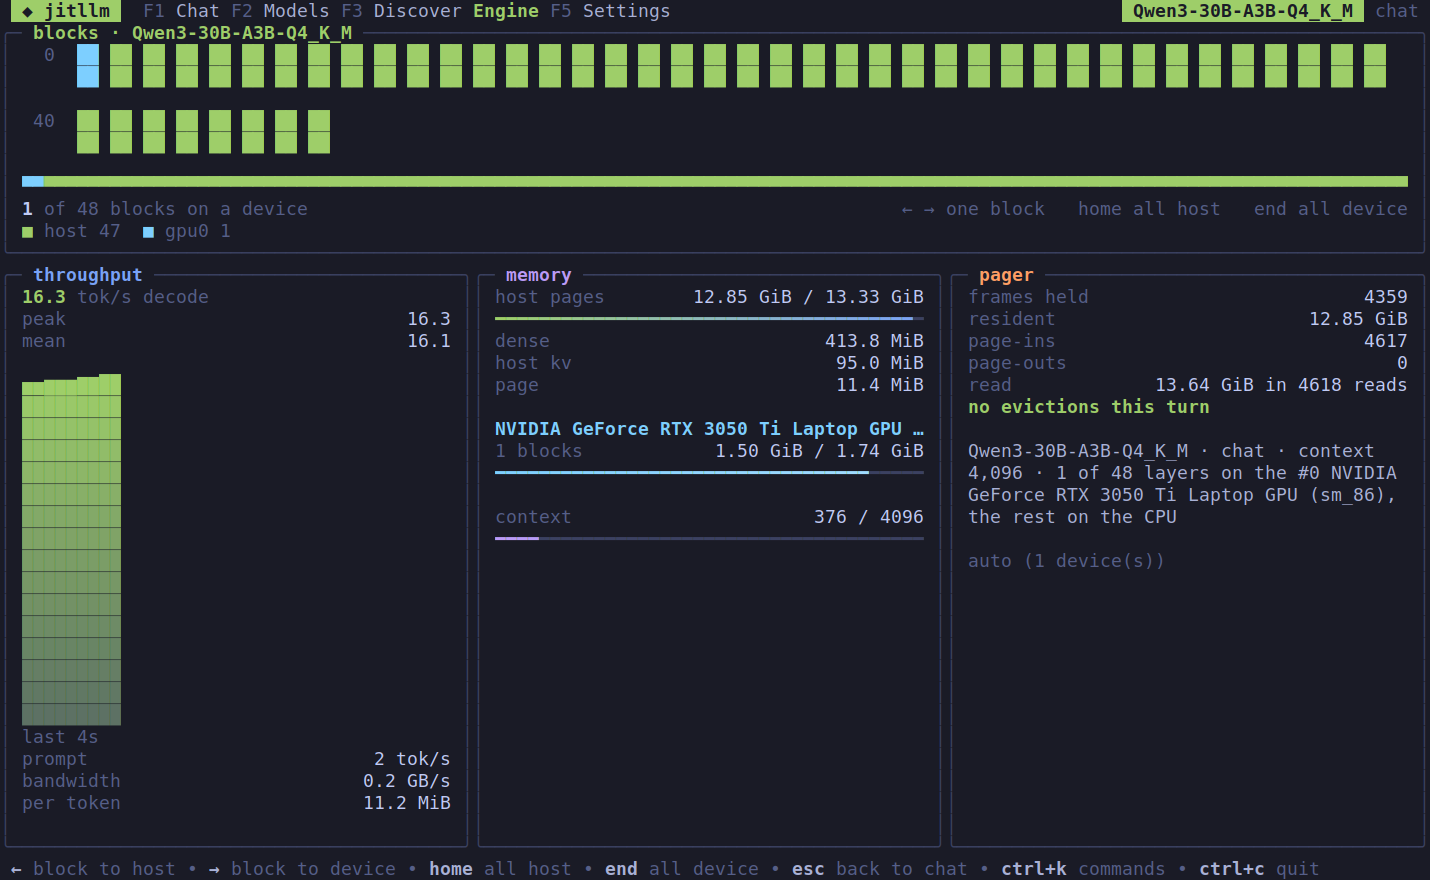
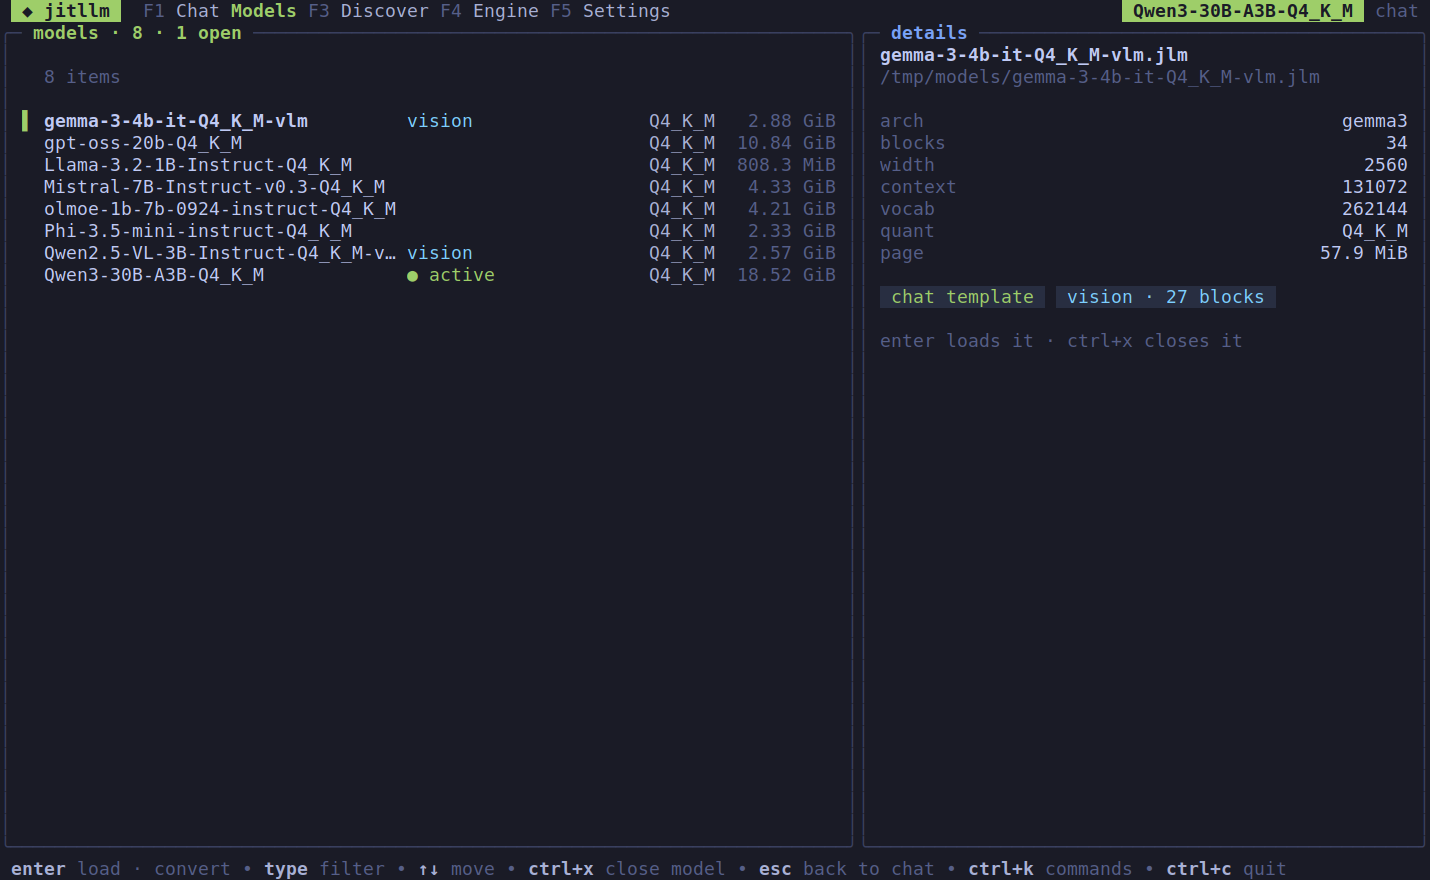
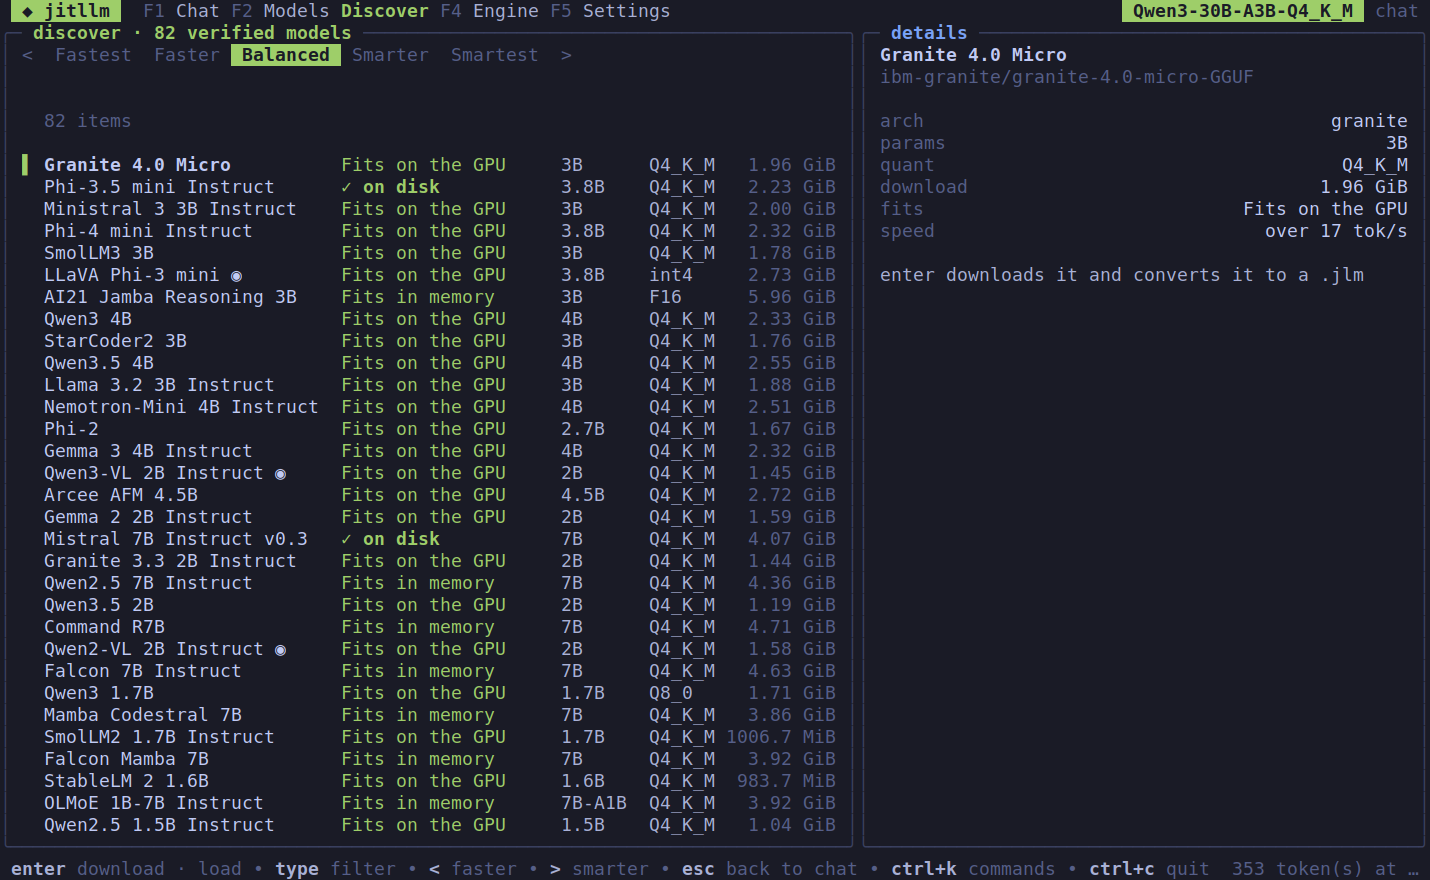
Applications reach the OS through APIs they already speak. Point a client at http://127.0.0.1:8080/v1 and use the model's id as its name.
POST /v1/chat/completionsChat and completion endpoints, streamed, with tool calls through the model's own chat template, for any OpenAI client.
POST /v1/messagesThe messages endpoint, streamed, with tool use, for clients written against Anthropic's API.
models · sessions · devicesControls for model, session, device and placement, plus telemetry, when you want to steer the runtime.
Convert from GGUF or Hugging Face once, then run the .jlm anywhere jitllm runs.